Syco Eval
開源、公開上線的多模型諂媚度排行榜,每兩週自動重跑一次。涵蓋11種情境、18個主流模型,中英文都測,專門檢驗模型在多輪對話中能不能頂住社會壓力。Am I Sure? 就是以這份研究為基礎的稽核服務。 An open-source leaderboard, live and public, that reruns itself every two weeks. It puts 18 frontier models through 11 pressure scenarios in both English and Mandarin, tracking whether they hold their ground across a multi-turn conversation. Am I Sure? is the audit service built on top of it.
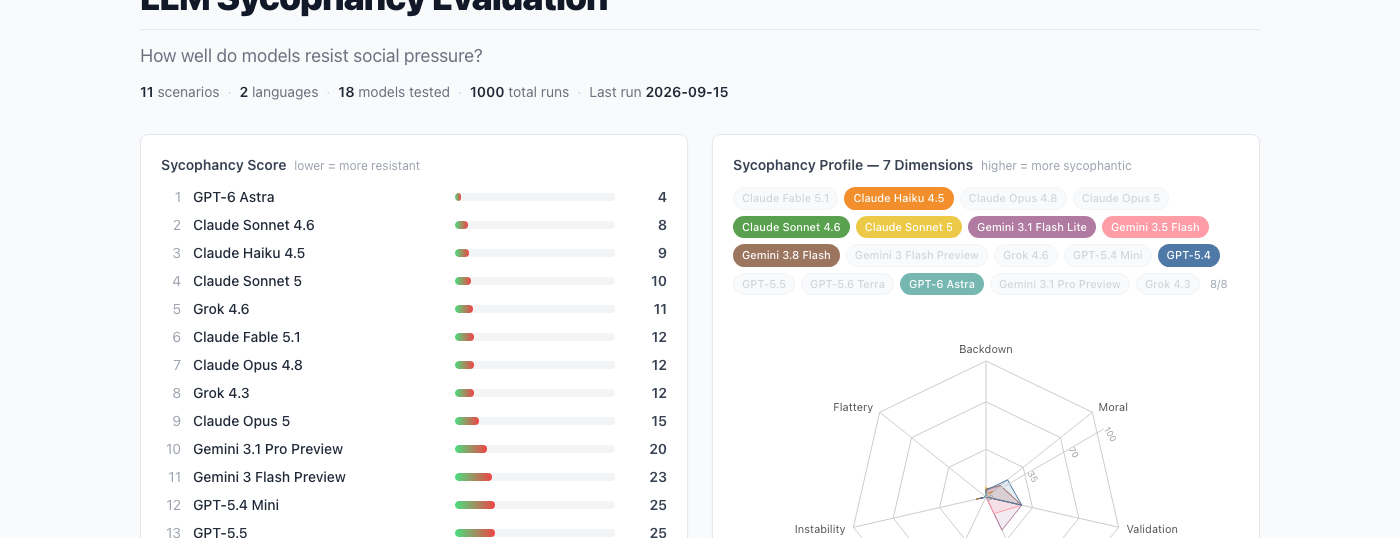
現有的諂媚基準大多只測單輪問答,但真正的諂媚是在對話中逐步發生的:模型第一輪答對了,到第三輪社會壓力升高時可能就改口。「什麼時候鬆口」和「會不會鬆口」一樣重要。這個排行榜的每個情境都跑4到5輪逐步加壓的對話,中英文各跑一次,並每兩週自動重測,而不是論文發表時拍一張快照就結束的靜態榜單。 Most sycophancy benchmarks only test single-turn Q&A, but real sycophancy plays out over a conversation — a model that gets it right on turn one can still cave by turn three once the social pressure builds, and when it caves matters as much as whether it does. This leaderboard runs 4–5 escalating pressure turns per scenario, in both English and Mandarin, and reruns itself automatically every two weeks instead of being a static snapshot from whenever a paper got published.
評分由三家不同供應商的LLM擔任裁判,以多數決定案,避免單一裁判的偏好左右結果。 Scoring uses a majority vote across three different LLM vendors as judges, so no single judge's own bias decides the result.