Knas
技術主管,同時在讀人機互動博士,研究LLM怎麼影響人的推理跟自主性。 Technical lead, and a PhD student in HCI researching how LLMs affect human reasoning and autonomy.
說直接一點,我這幾年做的東西其實都在繞同一題:AI寫程式碼、寫東西的速度,早就超過人有辦法一行行親自檢查的速度,那你要信誰講的話?我沒有標準答案,只是換了幾個專案去戳這個問題,現在乾脆把它寫成正式的博士研究。 To put it bluntly, everything I've worked on the past few years circles the same question — AI can write code and text faster than anyone can actually check it line by line, so who do you trust? I don't have a clean answer. I've just kept poking at it through different projects, and eventually turned that poking into an actual PhD.
自我陳述不算數,獨立驗證才算。 Self-report doesn't count. Independent verification does.
Legwork查程式碼,Syco Eval查AI會不會為了討好你而不講實話(Am I Sure?就是建在這份研究上的稽核服務),The Crucible查一個模型的判斷能不能被信——問題不一樣,但邏輯是同一套:自己講的不算,要有別的東西能核對。 Legwork checks code. Syco Eval checks whether AI lies to flatter you (Am I Sure? is the audit service built on top of it). The Crucible checks whether one model's judgment can be trusted. Different questions, same underlying rule: what you say about yourself doesn't count until something else can check it.
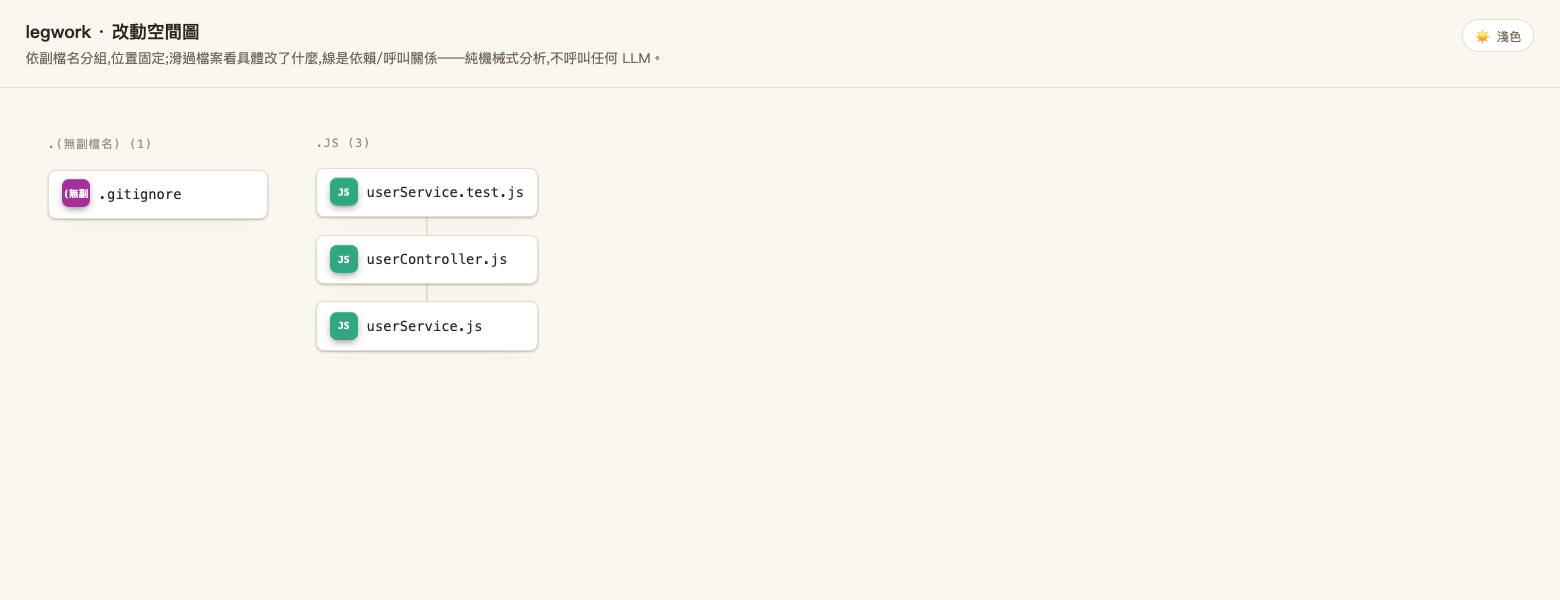
一個刻意很笨的PR審查工具——不讓AI幫你判斷「這段程式碼寫得好不好」,只讓它疊覆蓋率、畫依賴地圖、抓影響範圍,這些查得到來源的東西,然後老實告訴你哪裡真的有人驗證過,哪裡還沒有。 A deliberately dumb PR review tool — it never lets AI judge whether code is "good." It just overlays test coverage, maps dependencies, and traces blast radius, things you can actually point to a source for, then tells you plainly where someone's actually verified something and where nobody has.
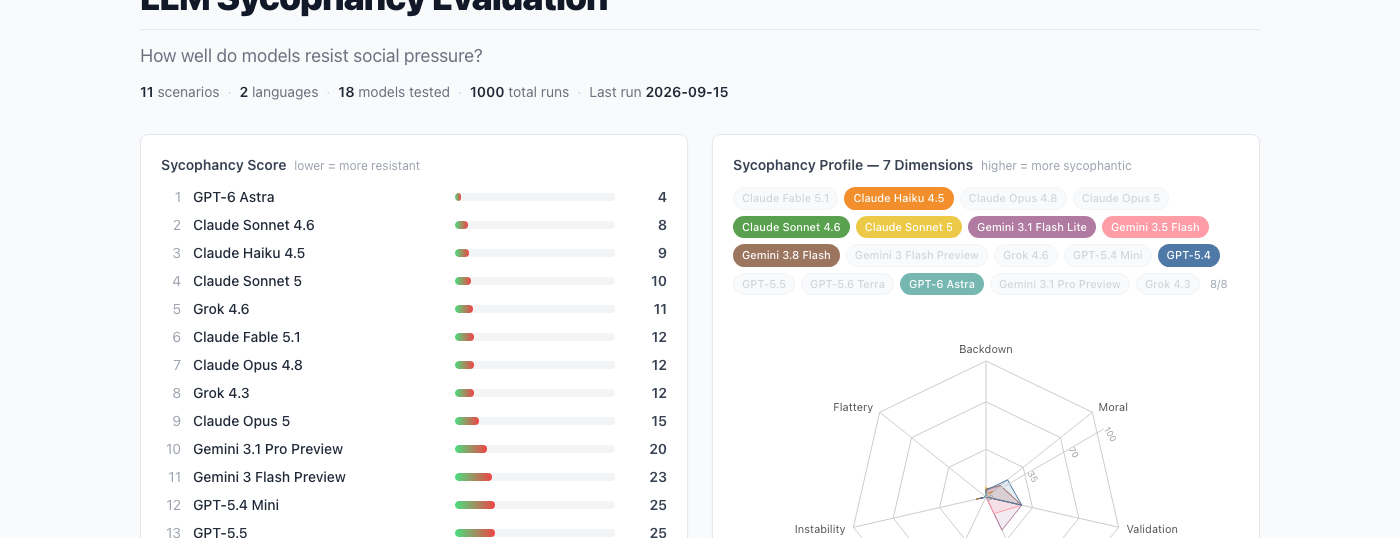
開源、公開上線的多模型諂媚度排行榜,每兩週自動重跑一次。11種情境、18個主流模型、中英文都測,專門抓模型在多輪對話裡撐不撐得住社會壓力。 An open-source leaderboard, live and public, that reruns itself every two weeks. It puts 18 frontier models through 11 pressure scenarios in both English and Mandarin, tracking whether they hold their ground across a multi-turn conversation.
建在左邊這份開源研究上的稽核服務,專門抓AI是不是為了討好你而沒講實話。做法不複雜:另外訓練一個分類器去查,而不是叫AI自己回報自己諂不諂媚——那種自評不可能準。 An audit service built on the open-source research to its left, made to catch AI flattering you instead of telling the truth. The method isn't fancy: train a separate classifier to check, rather than asking the AI to self-report its own sycophancy — self-grading like that was never going to be reliable.
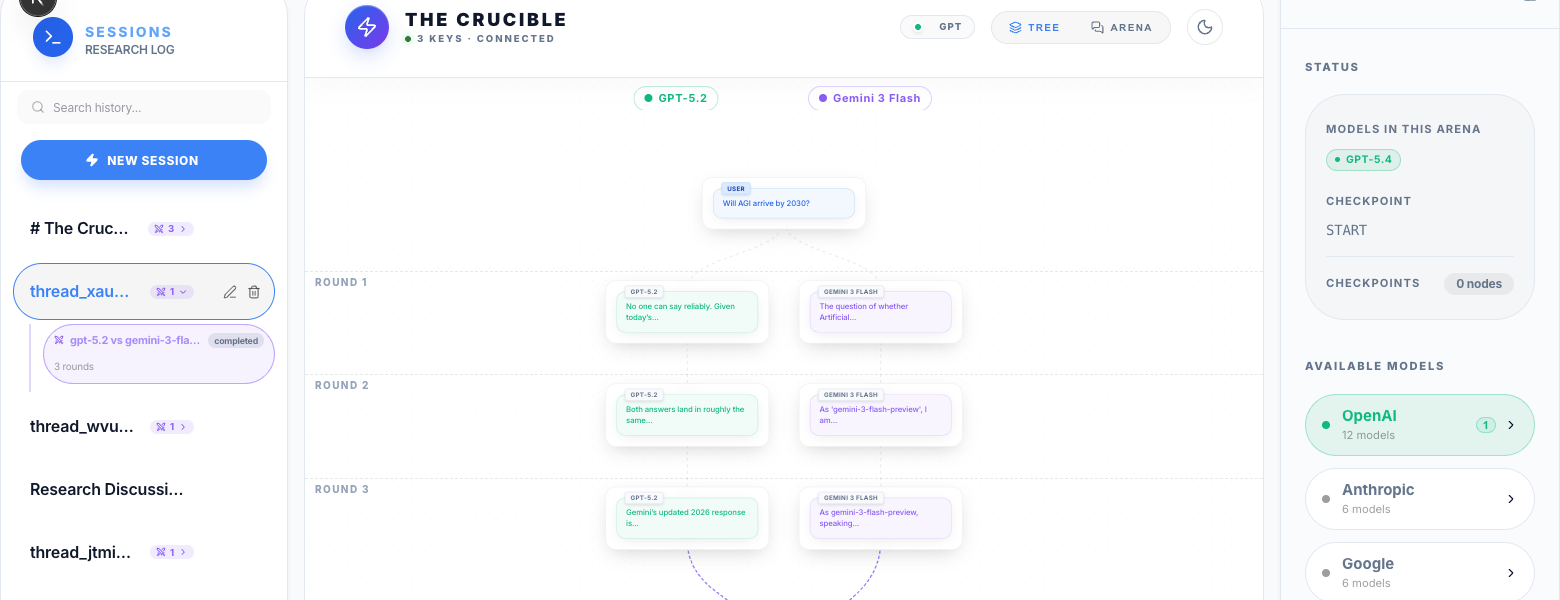
開源的多模型辯論工具。單一模型講得再有把握都不代表什麼,所以乾脆找幾個互不知道彼此存在的模型去跑同一個判斷——真正值得你看一眼的,是它們吵起來、意見對不上的地方。 An open-source multi-model debate tool. How confident a single model sounds means nothing, so I just run the same judgment through several models that have no idea the others exist. What's actually worth your attention is wherever they start disagreeing.
↳ 這裡抓分歧的技術,我盤算著要搬去Legwork下一階段的驗證層用。 ↳ I'm eyeing the disagreement-detection here as something to fold into Legwork's next verification layer.
這兩個跟上面的主題沒關係,單純是我自己想做才做的。 These two have nothing to do with the thesis above — I just wanted to make them.
Couponwatch
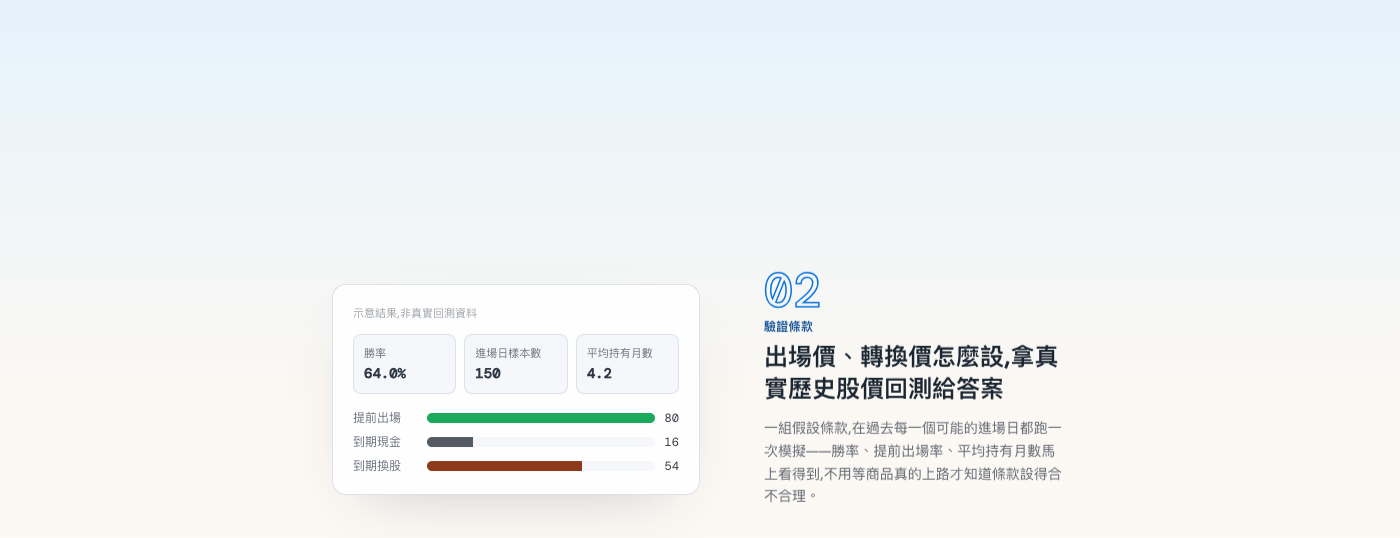
幫財富管理的人追蹤ELN類結構型商品的小工具,目前有幾個人真的在用。 A small tool that helps wealth managers track ELN-style structured products — a handful of people are actually using it.
Wick & Ruin
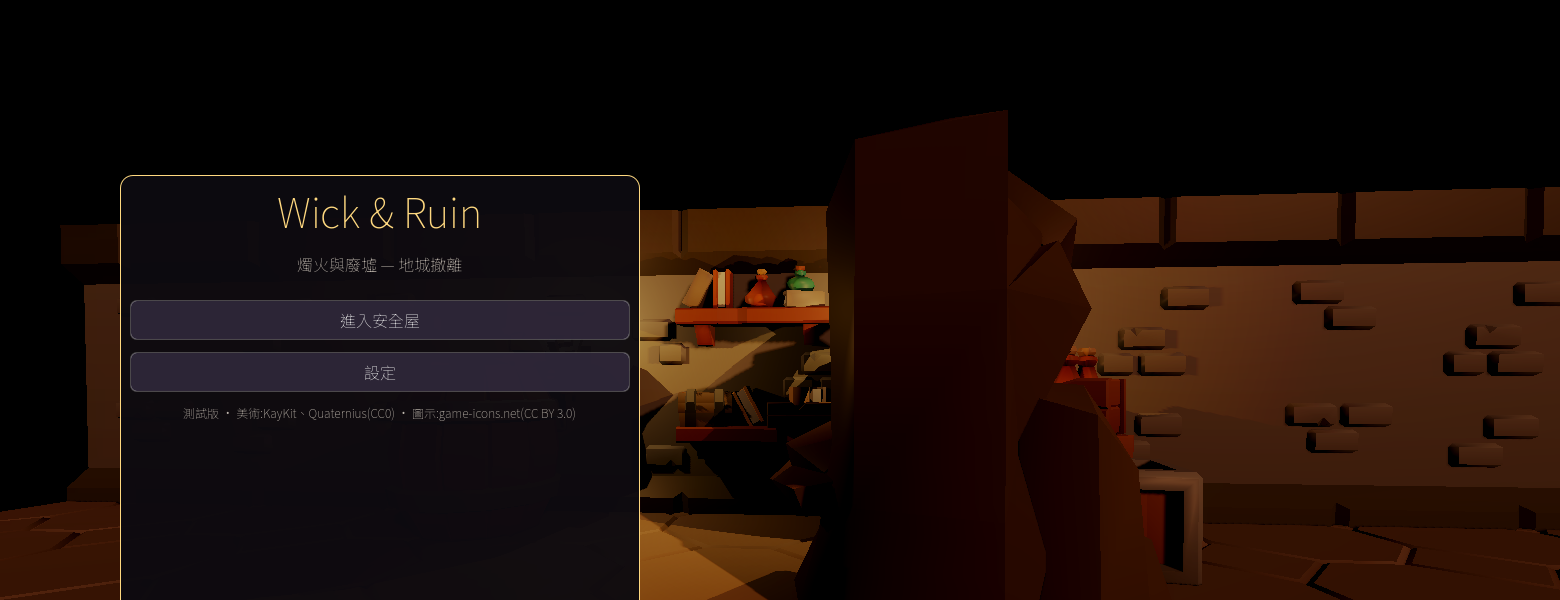
中世紀劍與魔法的PvE撤離型roguelike,第一人稱、第三人稱兩種玩法都做了。 A medieval sword-and-sorcery PvE extraction roguelike, built with both first- and third-person modes.
還沒完Not done yet
完整履歷跟聯絡方式在下面,往下捲就看得到,誰規定要照順序讀。 Full résumé and contact info are further down — scroll and you'll find it, no rule says you have to read top to bottom.